PEPMatch
The PEPMatch tool searches a set of peptides against a reference proteome, returning matches at or below a specified number of substitutions.
Methods
Finding short peptides in a large set of proteins is a different problem from general sequence alignment. Alignment tools such as BLAST were developed and optimised for longer sequences at lower similarity, and their recall drops for the short peptides used in immunology, typically 8 to 15 residues, where the matches of interest are identical or differ by only a few residues.
PEPMatch takes a non-alignment approach. It uses a deterministic k-mer mapping algorithm: the proteome is broken into all possible k-mers, each mapped to its index positions, and that mapping is stored as a key-value database. This preprocessing is done once per proteome and per value of k, and the resulting hash table gives very fast lookups once read into memory. Query peptides are broken into k-mers of the same size and looked up against it.
Because the method is deterministic rather than heuristic, recall is guaranteed rather than probabilistic. In the published benchmarks this gave roughly a 50-fold speed increase over BLAST without compromising recall.
Note
The value of k depends on the search. Exact searches use k=5, while searches allowing mismatches use k=3.
Reference: Marrama D, Chronister WD, Westernberg L, Vita R, Koşaloğlu-Yalçın Z, Sette A, Nielsen M, Greenbaum JA, Peters B. 2023. PEPMatch: a tool to identify short peptide sequence matches in large sets of proteins. BMC Bioinformatics 24(1):485. [PMID: 38110863]
Input Data

Enter one peptide sequence per line, in plain or FASTA format, into the Input Sequence(s) box. Each query peptide is scanned against the selected proteome.
Parameter Selection
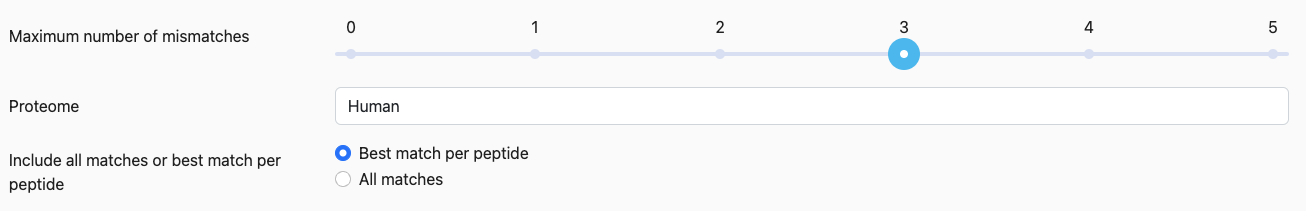
Maximum number of mismatches
The number of residue substitutions allowed when matching, from 0 to 5. PEPMatch returns hits at or below this number. A setting of 0 finds only exact matches.
Proteome
The set of proteins to search against. All included proteomes were obtained from UniProt/Swiss-Prot.
| Proteome | Taxon ID |
|---|---|
| Human | 9606 |
| Mouse | 10090 |
| Cow | 9913 |
| Dog | 9612 |
| Horse | 9796 |
| Pig | 9823 |
| Rabbit | 9986 |
| Rat | 10116 |
Include all matches or best match per peptide
This controls how many rows each query peptide produces.
Best match per peptide returns a single row per peptide: the match with the fewest substitutions.
All matches returns every match at or below the mismatch threshold, so one peptide can produce many rows.
The difference is substantial. The same five peptides searched against the human proteome at three mismatches return 5 rows under best match and 44 under all matches, because a peptide often matches several isoforms and related family members of its source protein.
Include unmatched peptides
By default, a peptide with no match at or below the threshold is dropped from the results, so the table can be shorter than the input. Enabling this option adds those peptides back as rows carrying only the input sequence, with the remaining fields empty.
Note
Use this when you need to account for every peptide submitted. Without it, a peptide missing from the results is indistinguishable from one you forgot to submit.
Results
The results table has one row per match, or one row per peptide under best match.
Five input peptides, five rows.

The same five peptides, 44 rows. Note that DDEDSKQNIFHFLYR alone matches five proteins exactly and a further four with one substitution.

| Column | Description |
|---|---|
| input sequence | The query peptide. |
| matched sequence | The matching peptide found in the proteome. Identical to the input when there are no mismatches. |
| protein id | UniProt/Swiss-Prot accession of the protein containing the match. |
| protein name | Name of that protein. |
| gene | Gene name associated with the match. |
| mismatches | Number of substitutions between the query and matched peptides. |
| mutated positions | Positions at which the two differ, as a list. Empty for an exact match. |
Further columns are available through Display Columns, including the species and taxon ID of the matched protein, its start and end index within the protein, and its protein existence level.
Interpreting Results
Mismatches and mutated positions read together. A row with 1 mismatch and [13] differs from the query at position 13 only. An exact match shows 0 and an empty list.
All matches reflects proteome redundancy, not weak matching. Most of the extra rows come from isoforms, fragments and closely related family members of the same protein, which is why RDX appears six times in the example above. Best match per peptide collapses that down when you want one answer per query.
Choose the mode to fit the question. Best match per peptide suits asking how closely a peptide resembles anything in the proteome, for example when assessing similarity to host sequences. All matches suits asking which proteins a peptide could have come from.